Income Inequality in Tertiary Enrollment by Network Type, Time Series (Wagstaff Index)
Overview
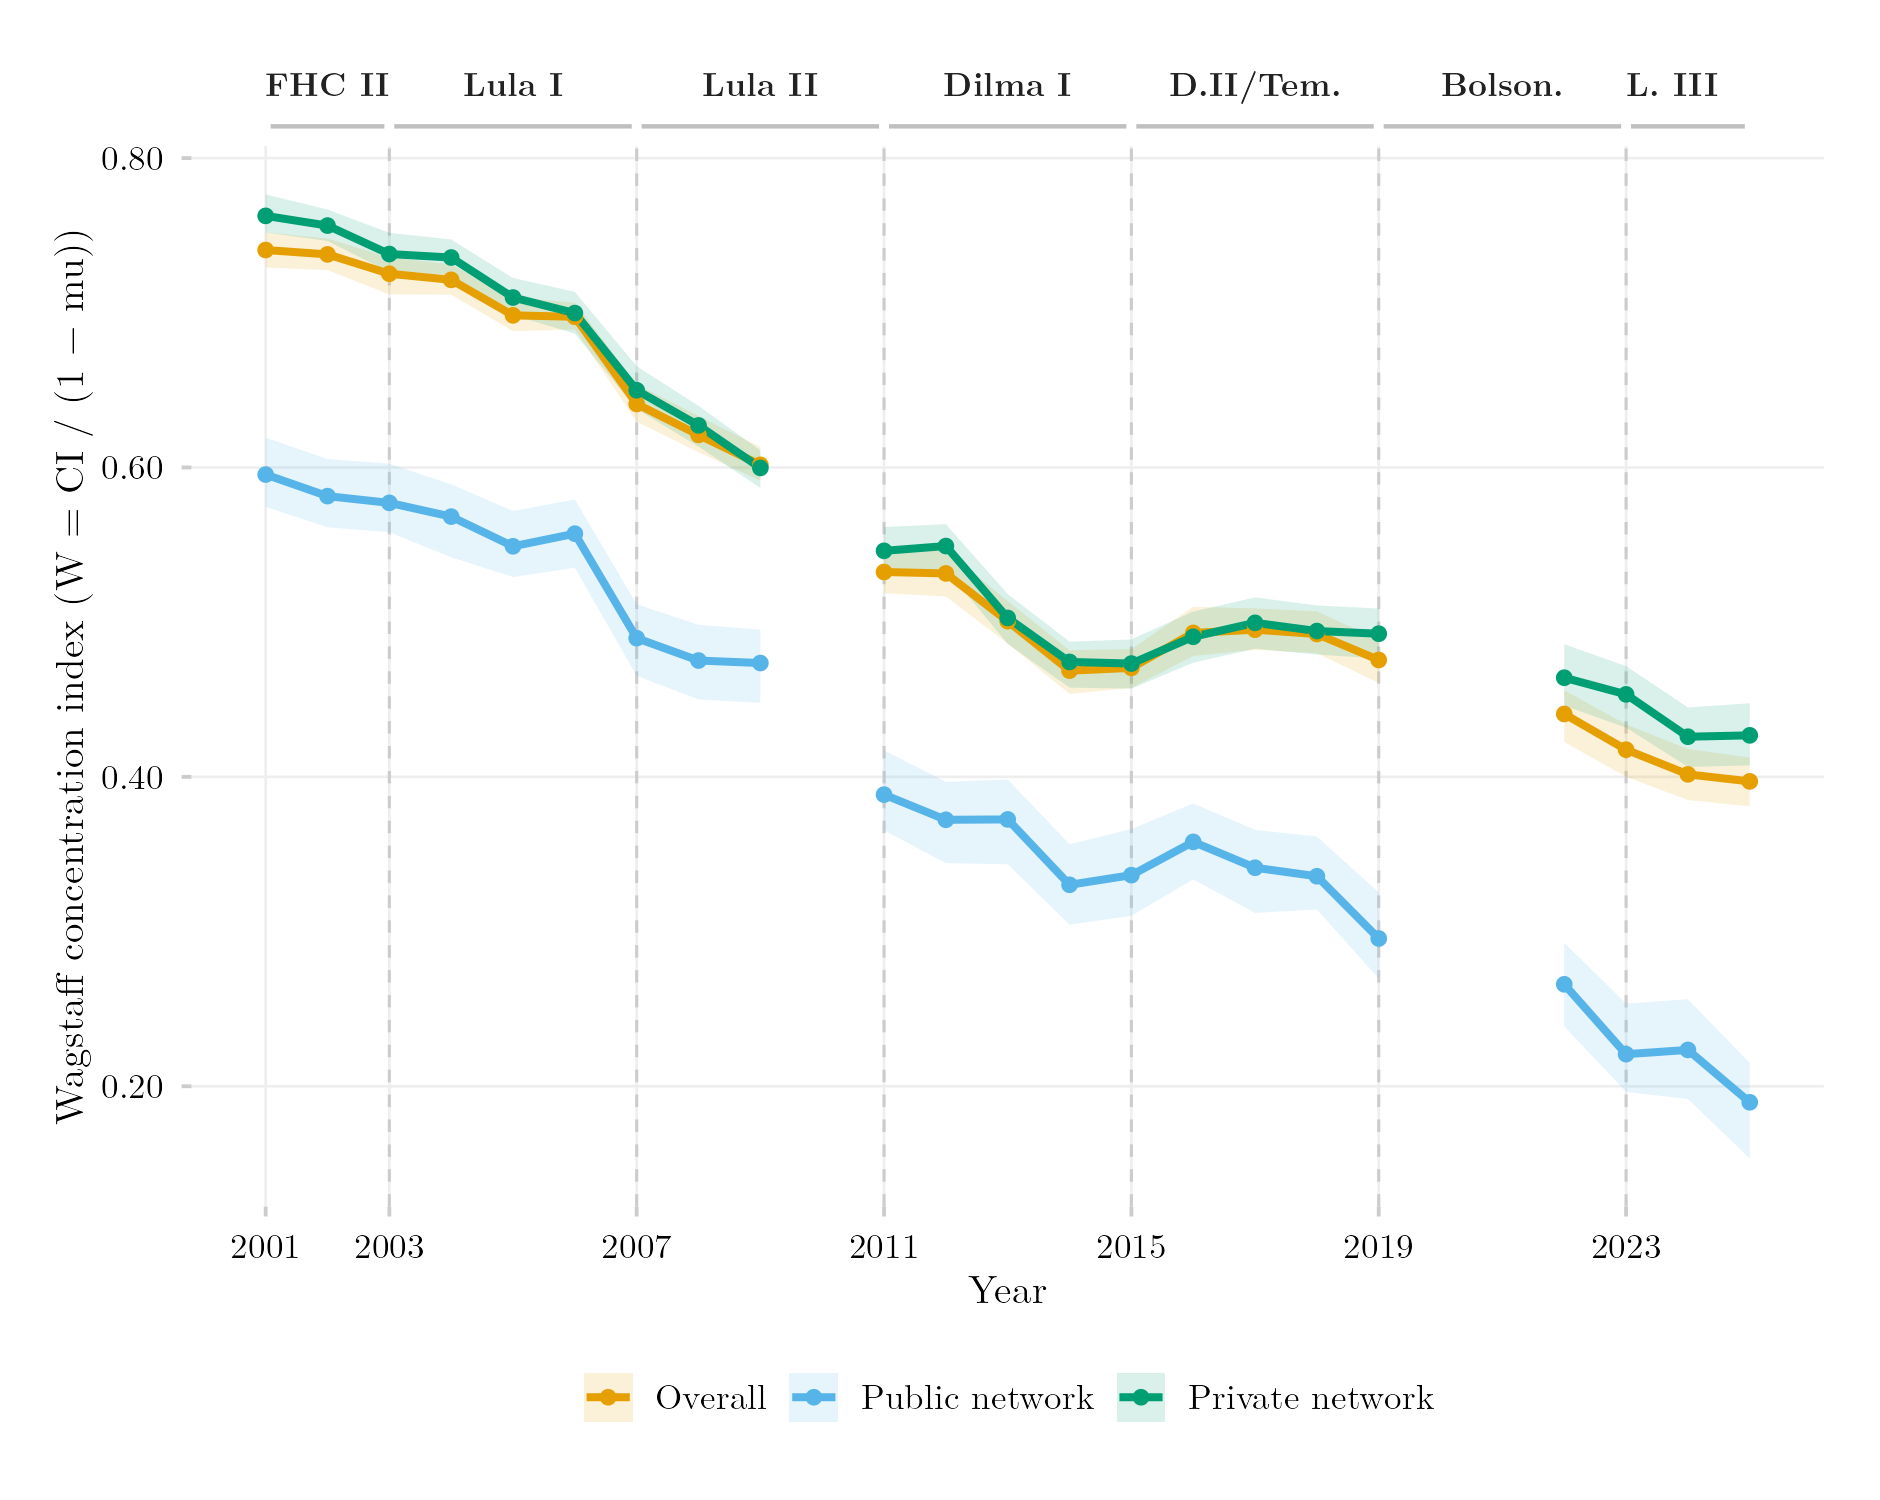
This figure tracks, over time, how concentrated enrollment in each network type — public vs. private higher education — is among higher-income households. Rather than looking at overall access, it applies the Wagstaff concentration index separately to enrollment in each network, allowing the two sectors’ income profiles to be compared directly and watched as they evolve.
Methodology
Time series of the Wagstaff concentration index applied to enrollment by network type (public vs. private), rather than to access overall — measuring whether enrollment in each network is concentrated among higher-income households, and how that concentration has moved over time. Computed directly from PNAD Anual and PNAD Contínua microdata, extracted standalone in this script rather than through the shared harmonized panel.
How to Cite
If you use this figure or the pipeline behind it, please cite both the dissertation and this specific analysis. References follow APA 7th edition.
Dissertation (in preparation; the entry will be updated after the defense):
Mançano, T. (2026). Inequality in access to tertiary education in Brazil: Household incomes, reforming policies, and the politics of who gets in (1990s–2020s) [Unpublished master’s thesis]. University of São Paulo.
This figure and pipeline:
Mançano, T. (2026, August 10). Income inequality in tertiary enrollment by network type, time series (Wagstaff index) [Figure and reproducible pipeline]. Open Data Analysis. https://mancano-tales.github.io/open-data-analysis/posts/wagstaff-rede-publica-privada-timeseries/
In text: (Mançano, 2026) — when citing several analyses from this catalog in the same work, APA distinguishes them as 2026a, 2026b, … in the order they appear in the reference list.
BibTeX:
@mastersthesis{Mancano2026Thesis,
  author = {Man\c{c}ano, Tales},
  title  = {Inequality in Access to Tertiary Education in Brazil: Household
            Incomes, Reforming Policies, and the Politics of Who Gets In
            (1990s--2020s)},
  school = {University of S\~{a}o Paulo},
  year   = {2026},
  type   = {Master's thesis},
  note   = {Unpublished; Graduate Program in Political Science}
}

@misc{Mancano2026_wagstaff_rede_publica_privada_timeseries,
  author       = {Man\c{c}ano, Tales},
  title        = {Income inequality in tertiary enrollment by network type, time series (Wagstaff index)},
  year         = {2026},
  month        = aug,
  howpublished = {Open Data Analysis, \url{https://mancano-tales.github.io/open-data-analysis/posts/wagstaff-rede-publica-privada-timeseries/}},
  note         = {Figure and reproducible pipeline. Source code: \url{https://github.com/mancano-tales/open-data-analysis}, folder posts/wagstaff-rede-publica-privada-timeseries/. Accessed YYYY-MM-DD}
}
A permanent version (Git tag + Zenodo DOI) will be linked here once the dissertation is defended; until then, cite the page URL above and add the date you accessed it (source code: https://github.com/mancano-tales/open-data-analysis, folder posts/wagstaff-rede-publica-privada-timeseries/).
Pipeline
Run these scripts in this order, from the project root (each one writes to data-raw/, which the next one reads):
shared-pipeline/pnadc/020_PNAD_Anual_Manual_Import_2001_2015.R— downloads the raw PNAD Anual 2001–2015 microdata (fixed-width.txt+ SAS layouts) from the IBGE FTP intodata-raw/pnad_anual_raw/<year>/—plot.Rreads these raw files directlyshared-pipeline/pnadc/000_PNADC_Download_Consolidate.R— (optional) pre-populates the PNAD Contínua cache indata-raw/pnadc_raw/; if you skip it,plot.Rdownloads the years it needs withPNADcIBGE::get_pnadc()into the same folderplot.R— reads the raw PNAD Anual files indata-raw/pnad_anual_raw/and the PNAD Contínua years indata-raw/pnadc_raw/; caches its extraction and bootstrap indata-raw/rede-publica-privada/(sourcesshared-pipeline/utils/codigos_curso_pnad.R); writes the figure tooutput/figures/wagstaff-rede-publica-privada-timeseries/— compare it with this post’sthumbnail.png
Reproducibility
Tier: A
This pipeline uses only public data, accessible via package/API without any credential (PNADcIBGE, censobr, sidrar, ipeadatar). Run the scripts in shared-pipeline/ in numeric order to reconstruct the intermediate data.