Income Concentration in Tertiary Enrollment by Network Type
Overview
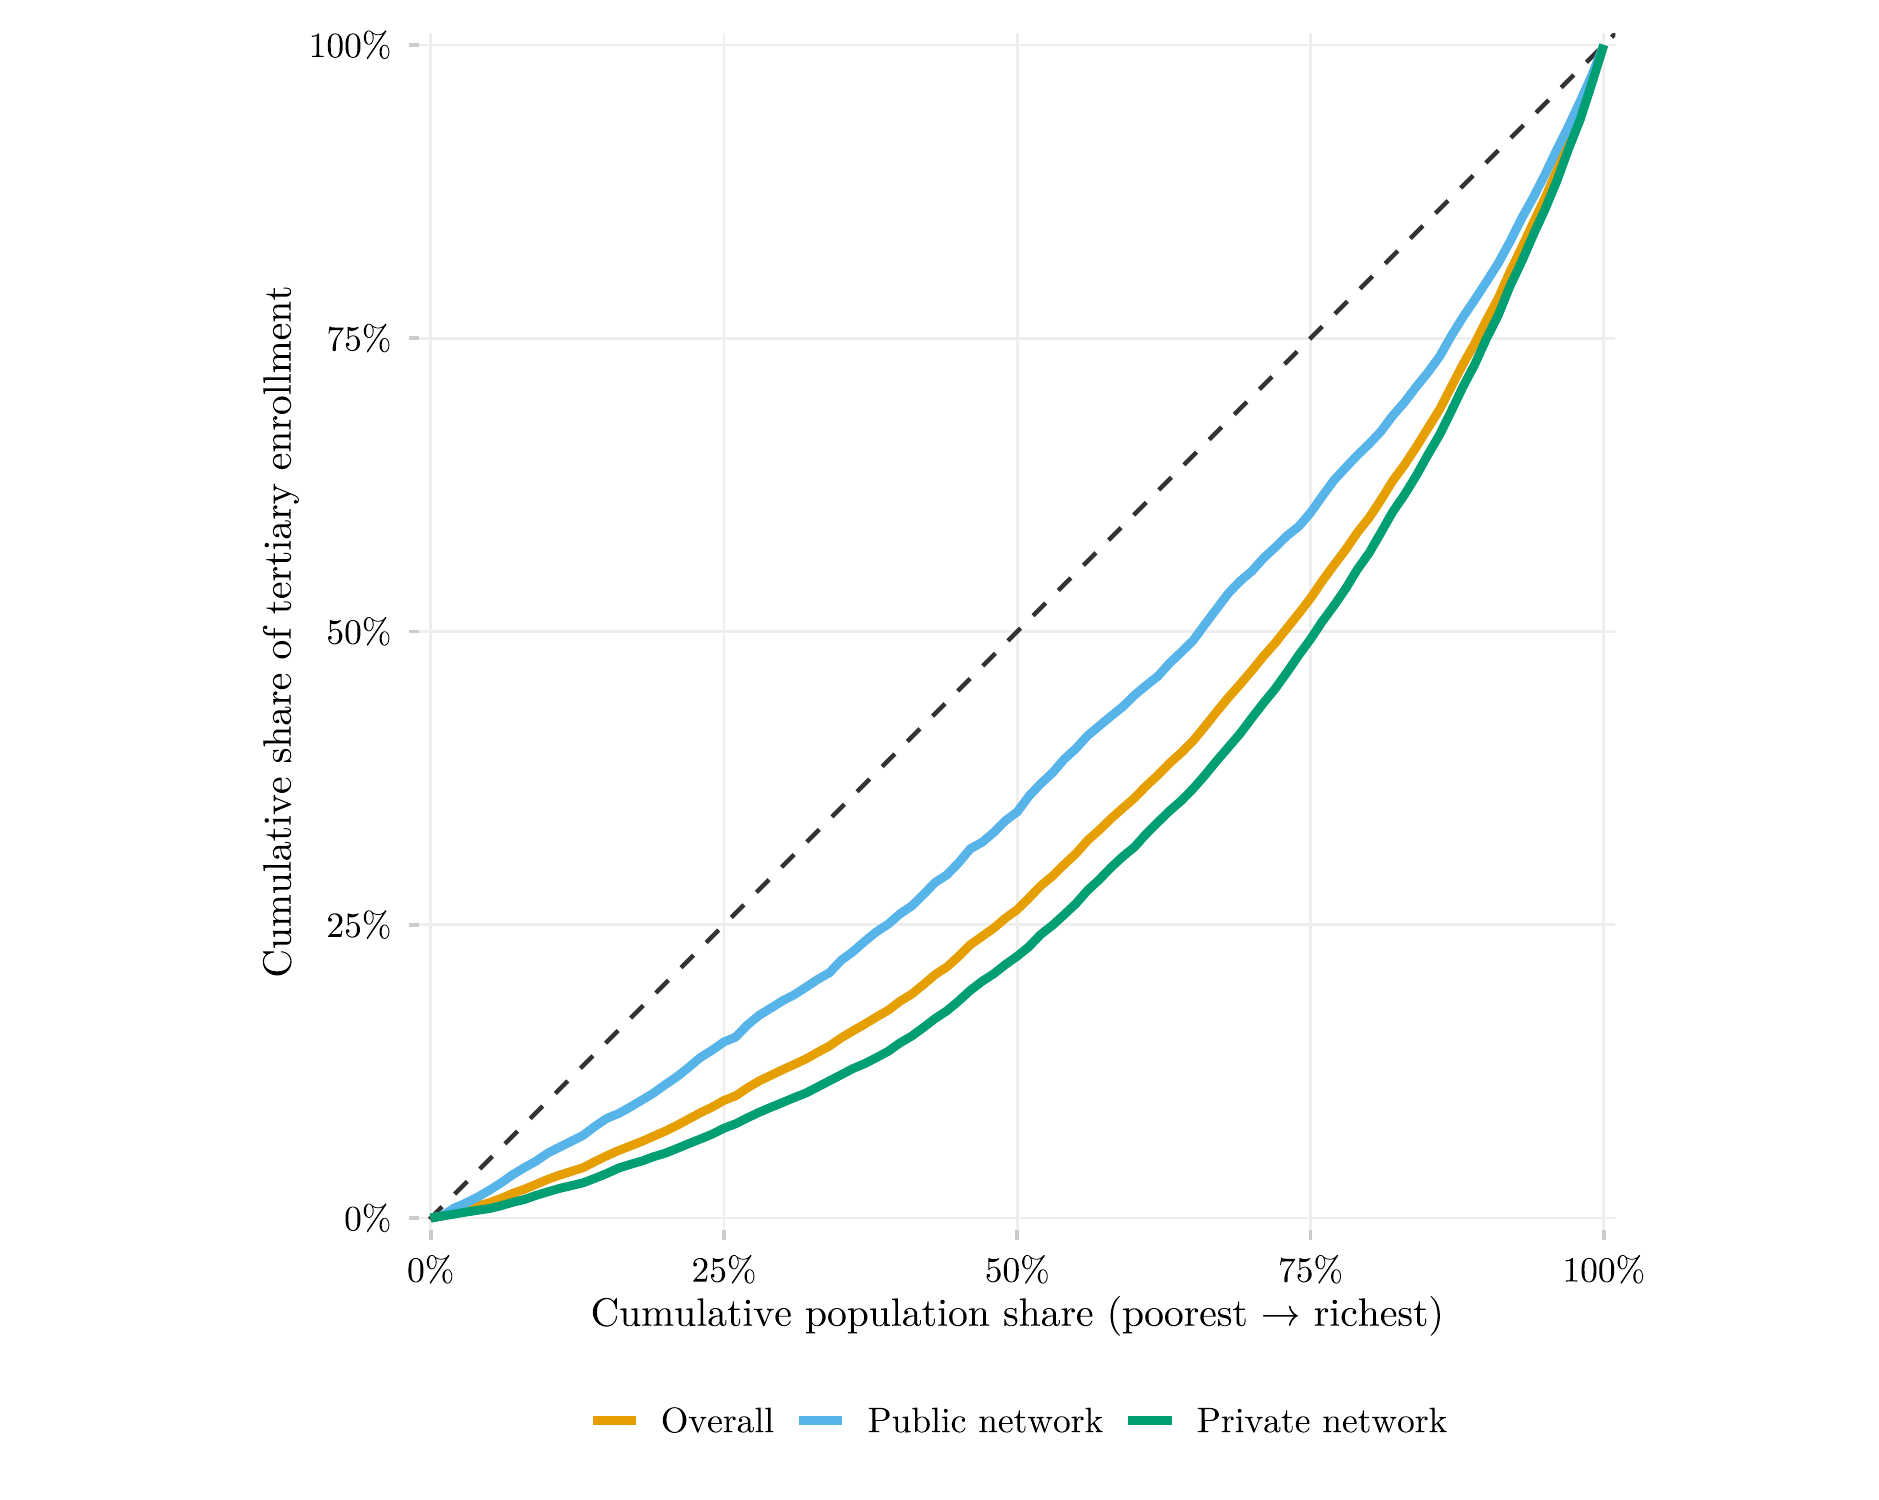
This figure compares income concentration curves for general tertiary-education enrollment against enrollment in the public network specifically and the private network specifically, for 18–24-year-olds, pooling the most recent stable years (2022–2024). It shows which of the two sectors draws more heavily from higher-income households.
Methodology
Curves show, for each network, the cumulative share of currently enrolled tertiary students accounted for by the poorest p% of the 18–24-year-old population, ranked by per-capita household income within each year. The closer a curve sits to the 45-degree line, the more evenly access to that network is distributed across the income distribution; curves bowing below the diagonal indicate concentration among higher-income deciles. The pooled curve is a simple average of the year-specific curves for 2022, 2023, and 2024 (each resampled on a uniform 101-point percentile grid), so each year contributes equally regardless of sample size. The Erreygers concentration index is computed year by year for the same three years. The network variable is V3002A (IBGE PNADC) rather than the V3004-derived network variable used elsewhere in this project, since V3004 never covers tertiary students in any year; V3002A is its 2015+ replacement, with reversed coding (1 = private, 2 = public) relative to the V3004 convention.
How to Cite
If you use this figure or the pipeline behind it, please cite both the dissertation and this specific analysis. References follow APA 7th edition.
Dissertation (in preparation; the entry will be updated after the defense):
Mançano, T. (2026). Inequality in access to tertiary education in Brazil: Household incomes, reforming policies, and the politics of who gets in (1990s–2020s) [Unpublished master’s thesis]. University of São Paulo.
This figure and pipeline:
Mançano, T. (2026, July 6). Income concentration in tertiary enrollment by network type [Figure and reproducible pipeline]. Open Data Analysis. https://mancano-tales.github.io/open-data-analysis/posts/concentracao-rede-publica-privada/
In text: (Mançano, 2026) — when citing several analyses from this catalog in the same work, APA distinguishes them as 2026a, 2026b, … in the order they appear in the reference list.
BibTeX:
@mastersthesis{Mancano2026Thesis,
  author = {Man\c{c}ano, Tales},
  title  = {Inequality in Access to Tertiary Education in Brazil: Household
            Incomes, Reforming Policies, and the Politics of Who Gets In
            (1990s--2020s)},
  school = {University of S\~{a}o Paulo},
  year   = {2026},
  type   = {Master's thesis},
  note   = {Unpublished; Graduate Program in Political Science}
}

@misc{Mancano2026_concentracao_rede_publica_privada,
  author       = {Man\c{c}ano, Tales},
  title        = {Income concentration in tertiary enrollment by network type},
  year         = {2026},
  month        = jul,
  howpublished = {Open Data Analysis, \url{https://mancano-tales.github.io/open-data-analysis/posts/concentracao-rede-publica-privada/}},
  note         = {Figure and reproducible pipeline. Source code: \url{https://github.com/mancano-tales/open-data-analysis}, folder posts/concentracao-rede-publica-privada/. Accessed YYYY-MM-DD}
}
A permanent version (Git tag + Zenodo DOI) will be linked here once the dissertation is defended; until then, cite the page URL above and add the date you accessed it (source code: https://github.com/mancano-tales/open-data-analysis, folder posts/concentracao-rede-publica-privada/).
Pipeline
Run these scripts in this order, from the project root (each one writes to data-raw/, which the next one reads):
shared-pipeline/pnadc/000_PNADC_Download_Consolidate.R— (optional) pre-populates the PNAD Contínua cache indata-raw/pnadc_raw/; if you skip it,plot.Rdownloads the years it needs withPNADcIBGE::get_pnadc()into the same folderplot.R— downloads PNAD Contínua 2022–2024 withPNADcIBGE::get_pnadc()intodata-raw/pnadc_raw/and builds the figure directly from the microdata; writes the figure tooutput/figures/concentracao-rede-publica-privada/— compare it with this post’sthumbnail.png
Reproducibility
Tier: A
This pipeline uses only public data, accessible via package/API without any credential (PNADcIBGE, censobr, sidrar, ipeadatar). Run the scripts in shared-pipeline/ in numeric order to reconstruct the intermediate data.